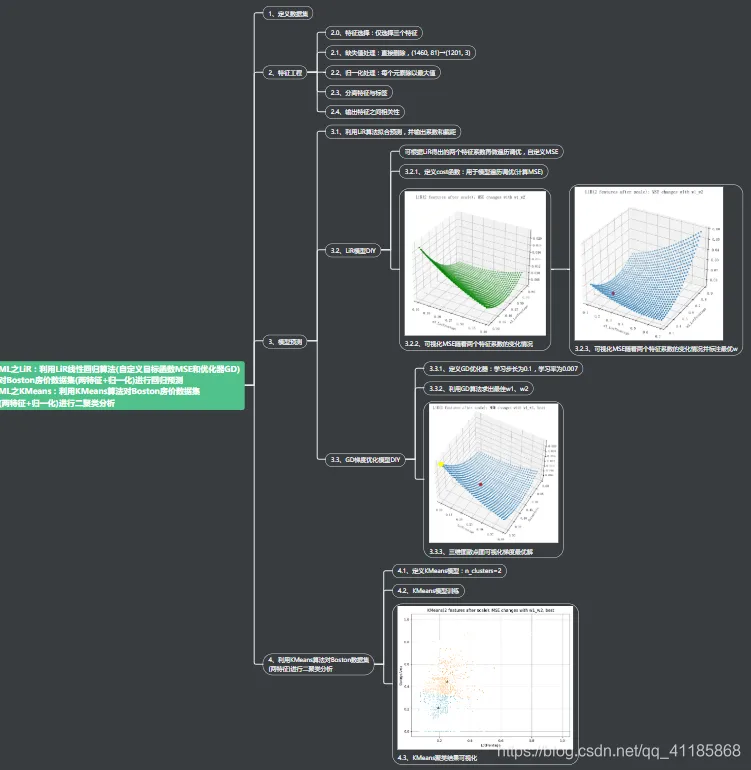
设计思路
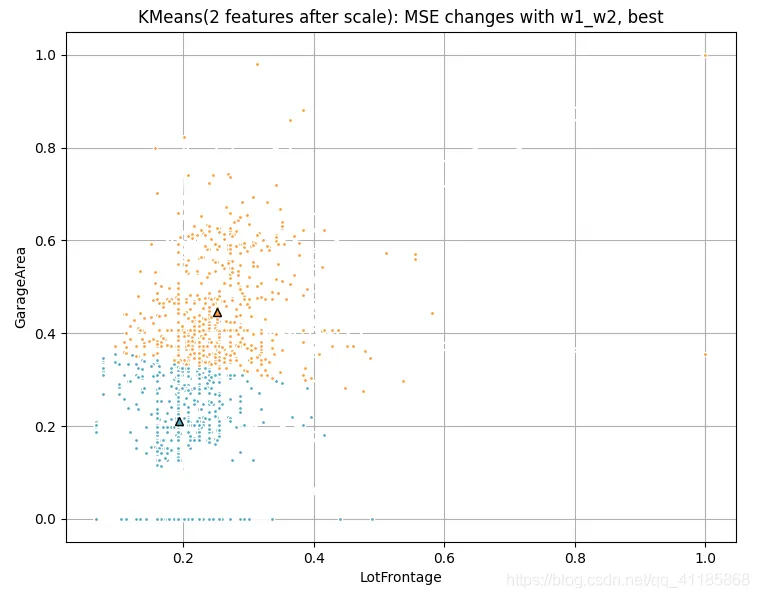
输出结果
train_boston_data.shape (1460, 81)
Id MSSubClass MSZoning ... SaleType SaleCondition SalePrice
0 1 60 RL ... WD Normal 208500
1 2 20 RL ... WD Normal 181500
2 3 60 RL ... WD Normal 223500
3 4 70 RL ... WD Abnorml 140000
4 5 60 RL ... WD Normal 250000
[5 rows x 81 columns]
train_t.head() LotFrontage GarageArea SalePrice
0 65.0 548 208500
1 80.0 460 181500
2 68.0 608 223500
3 60.0 642 140000
4 84.0 836 250000
after scale,train_t.head() LotFrontage GarageArea SalePrice
0 0.207668 0.386460 0.276159
1 0.255591 0.324401 0.240397
2 0.217252 0.428773 0.296026
3 0.191693 0.452750 0.185430
4 0.268371 0.589563 0.331126
LotFrontage GarageArea
0 0.207668 0.386460
1 0.255591 0.324401
2 0.217252 0.428773
3 0.191693 0.452750
4 0.268371 0.589563
Id MSSubClass LotFrontage ... MoSold YrSold SalePrice
Id 1.000000 0.011156 -0.010601 ... 0.021172 0.000712 -0.021917
MSSubClass 0.011156 1.000000 -0.386347 ... -0.013585 -0.021407 -0.084284
LotFrontage -0.010601 -0.386347 1.000000 ... 0.011200 0.007450 0.351799
LotArea -0.033226 -0.139781 0.426095 ... 0.001205 -0.014261 0.263843
OverallQual -0.028365 0.032628 0.251646 ... 0.070815 -0.027347 0.790982
OverallCond 0.012609 -0.059316 -0.059213 ... -0.003511 0.043950 -0.077856
YearBuilt -0.012713 0.027850 0.123349 ... 0.012398 -0.013618 0.522897
YearRemodAdd -0.021998 0.040581 0.088866 ... 0.021490 0.035743 0.507101
MasVnrArea -0.050298 0.022936 0.193458 ... -0.005965 -0.008201 0.477493
BsmtFinSF1 -0.005024 -0.069836 0.233633 ... -0.015727 0.014359 0.386420
BsmtFinSF2 -0.005968 -0.065649 0.049900 ... -0.015211 0.031706 -0.011378
BsmtUnfSF -0.007940 -0.140759 0.132644 ... 0.034888 -0.041258 0.214479
TotalBsmtSF -0.015415 -0.238518 0.392075 ... 0.013196 -0.014969 0.613581
1stFlrSF 0.010496 -0.251758 0.457181 ... 0.031372 -0.013604 0.605852
2ndFlrSF 0.005590 0.307886 0.080177 ... 0.035164 -0.028700 0.319334
LowQualFinSF -0.044230 0.046474 0.038469 ... -0.022174 -0.028921 -0.025606
GrLivArea 0.008273 0.074853 0.402797 ... 0.050240 -0.036526 0.708624
BsmtFullBath 0.002289 0.003491 0.100949 ... -0.025361 0.067049 0.227122
BsmtHalfBath -0.020155 -0.002333 -0.007234 ... 0.032873 -0.046524 -0.016844
FullBath 0.005587 0.131608 0.198769 ... 0.055872 -0.019669 0.560664
HalfBath 0.006784 0.177354 0.053532 ... -0.009050 -0.010269 0.284108
BedroomAbvGr 0.037719 -0.023438 0.263170 ... 0.046544 -0.036014 0.168213
KitchenAbvGr 0.002951 0.281721 -0.006069 ... 0.026589 0.031687 -0.135907
TotRmsAbvGrd 0.027239 0.040380 0.352096 ... 0.036907 -0.034516 0.533723
Fireplaces -0.019772 -0.045569 0.266639 ... 0.046357 -0.024096 0.466929
GarageYrBlt 0.000072 0.085072 0.070250 ... 0.005337 -0.001014 0.486362
GarageCars 0.016570 -0.040110 0.285691 ... 0.040522 -0.039117 0.640409
GarageArea 0.017634 -0.098672 0.344997 ... 0.027974 -0.027378 0.623431
WoodDeckSF -0.029643 -0.012579 0.088521 ... 0.021011 0.022270 0.324413
OpenPorchSF -0.000477 -0.006100 0.151972 ... 0.071255 -0.057619 0.315856
EnclosedPorch 0.002889 -0.012037 0.010700 ... -0.028887 -0.009916 -0.128578
3SsnPorch -0.046635 -0.043825 0.070029 ... 0.029474 0.018645 0.044584
ScreenPorch 0.001330 -0.026030 0.041383 ... 0.023217 0.010694 0.111447
PoolArea 0.057044 0.008283 0.206167 ... -0.033737 -0.059689 0.092404
MiscVal -0.006242 -0.007683 0.003368 ... -0.006495 0.004906 -0.021190
MoSold 0.021172 -0.013585 0.011200 ... 1.000000 -0.145721 0.046432
YrSold 0.000712 -0.021407 0.007450 ... -0.145721 1.000000 -0.028923
SalePrice -0.021917 -0.084284 0.351799 ... 0.046432 -0.028923 1.000000
[38 rows x 38 columns]
k_means_cluster_centers
[[0.1938454 0.21080405]
[0.25140958 0.44595543]]
k_means_labels_unique
[0 1]
0 [1 1 1 ... 0 0 0]
0 [1 1 1 ... 0 0 0] [False False False ... True True True]
1 [1 1 1 ... 0 0 0]
1 [1 1 1 ... 0 0 0] [ True True True ... False False False]
核心代码
class KMeans Found at: sklearn.cluster._kmeans
class KMeans(TransformerMixin, ClusterMixin, BaseEstimator):
"""K-Means clustering.
Read more in the :ref:`User Guide <k_means>`.
Parameters
----------
n_clusters : int, default=8
The number of clusters to form as well as the number of
centroids to generate.
init : {'k-means++', 'random', ndarray, callable}, default='k-
means++'
Method for initialization:
'k-means++' : selects initial cluster centers for k-mean
clustering in a smart way to speed up convergence. See
section
Notes in k_init for more details.
'random': choose `n_clusters` observations (rows) at
random from data
for the initial centroids.
If an ndarray is passed, it should be of shape (n_clusters,
n_features)
and gives the initial centers.
If a callable is passed, it should take arguments X,
n_clusters and a
random state and return an initialization.
n_init : int, default=10
Number of time the k-means algorithm will be run with
different
centroid seeds. The final results will be the best output of
n_init consecutive runs in terms of inertia.
max_iter : int, default=300
Maximum number of iterations of the k-means algorithm
for a
single run.
tol : float, default=1e-4
Relative tolerance with regards to Frobenius norm of the
difference
in the cluster centers of two consecutive iterations to
declare
convergence.
It's not advised to set `tol=0` since convergence might
never be
declared due to rounding errors. Use a very small number
instead.
precompute_distances : {'auto', True, False}, default='auto'
Precompute distances (faster but takes more memory).
'auto' : do not precompute distances if n_samples *
n_clusters > 12
million. This corresponds to about 100MB overhead per
job using
double precision.
True : always precompute distances.
False : never precompute distances.
.. deprecated:: 0.23
'precompute_distances' was deprecated in version 0.22
and will be
removed in 0.25. It has no effect.
verbose : int, default=0
Verbosity mode.
random_state : int, RandomState instance, default=None
Determines random number generation for centroid
initialization. Use
an int to make the randomness deterministic.
See :term:`Glossary <random_state>`.
copy_x : bool, default=True
When pre-computing distances it is more numerically
accurate to center
the data first. If copy_x is True (default), then the original
data is
not modified. If False, the original data is modified, and put
back
before the function returns, but small numerical
differences may be
introduced by subtracting and then adding the data mean.
Note that if
the original data is not C-contiguous, a copy will be made
even if
copy_x is False. If the original data is sparse, but not in CSR
format,
a copy will be made even if copy_x is False.
n_jobs : int, default=None
The number of OpenMP threads to use for the
computation. Parallelism is
sample-wise on the main cython loop which assigns each
sample to its
closest center.
``None`` or ``-1`` means using all processors.
.. deprecated:: 0.23
``n_jobs`` was deprecated in version 0.23 and will be
removed in
0.25.
algorithm : {"auto", "full", "elkan"}, default="auto"
K-means algorithm to use. The classical EM-style algorithm
is "full".
The "elkan" variation is more efficient on data with well-
defined
clusters, by using the triangle inequality. However it's
more memory
intensive due to the allocation of an extra array of shape
(n_samples, n_clusters).
For now "auto" (kept for backward compatibiliy) chooses
"elkan" but it
might change in the future for a better heuristic.
.. versionchanged:: 0.18
Added Elkan algorithm
Attributes
----------
cluster_centers_ : ndarray of shape (n_clusters, n_features)
Coordinates of cluster centers. If the algorithm stops
before fully
converging (see ``tol`` and ``max_iter``), these will not be
consistent with ``labels_``.
labels_ : ndarray of shape (n_samples,)
Labels of each point
inertia_ : float
Sum of squared distances of samples to their closest
cluster center.
n_iter_ : int
Number of iterations run.
See also
--------
MiniBatchKMeans
Alternative online implementation that does incremental
updates
of the centers positions using mini-batches.
For large scale learning (say n_samples > 10k)
MiniBatchKMeans is
probably much faster than the default batch
implementation.
Notes
-----
The k-means problem is solved using either Lloyd's or
Elkan's algorithm.
The average complexity is given by O(k n T), were n is the
number of
samples and T is the number of iteration.
The worst case complexity is given by O(n^(k+2/p)) with
n = n_samples, p = n_features. (D. Arthur and S. Vassilvitskii,
'How slow is the k-means method?' SoCG2006)
In practice, the k-means algorithm is very fast (one of the
fastest
clustering algorithms available), but it falls in local minima.
That's why
it can be useful to restart it several times.
If the algorithm stops before fully converging (because of
``tol`` or
``max_iter``), ``labels_`` and ``cluster_centers_`` will not be
consistent,
i.e. the ``cluster_centers_`` will not be the means of the
points in each
cluster. Also, the estimator will reassign ``labels_`` after the
last
iteration to make ``labels_`` consistent with ``predict`` on
the training
set.
Examples
--------
>>> from sklearn.cluster import KMeans
>>> import numpy as np
>>> X = np.array([[1, 2], [1, 4], [1, 0],
... [10, 2], [10, 4], [10, 0]])
>>> kmeans = KMeans(n_clusters=2, random_state=0).fit
(X)
>>> kmeans.labels_
array([1, 1, 1, 0, 0, 0], dtype=int32)
>>> kmeans.predict([[0, 0], [12, 3]])
array([1, 0], dtype=int32)
>>> kmeans.cluster_centers_
array([[10., 2.],
[ 1., 2.]])
"""
@_deprecate_positional_args
def __init__(self, n_clusters=8, *, init='k-means++',
n_init=10,
max_iter=300, tol=1e-4,
precompute_distances='deprecated',
verbose=0, random_state=None, copy_x=True,
n_jobs='deprecated', algorithm='auto'):
self.n_clusters = n_clusters
self.init = init
self.max_iter = max_iter
self.tol = tol
self.precompute_distances = precompute_distances
self.n_init = n_init
self.verbose = verbose
self.random_state = random_state
self.copy_x = copy_x
self.n_jobs = n_jobs
self.algorithm = algorithm
def _check_test_data(self, X):
X = check_array(X, accept_sparse='csr', dtype=[np.
float64, np.float32],
order='C', accept_large_sparse=False)
n_samples, n_features = X.shape
expected_n_features = self.cluster_centers_.shape[1]
if not n_features == expected_n_features:
raise ValueError(
"Incorrect number of features. "
"Got %d features, expected %d" %
(n_features, expected_n_features))
return X
def fit(self, X, y=None, sample_weight=None):
"""Compute k-means clustering.
Parameters
----------
X : {array-like, sparse matrix} of shape (n_samples,
n_features)
Training instances to cluster. It must be noted that the
data
will be converted to C ordering, which will cause a
memory
copy if the given data is not C-contiguous.
If a sparse matrix is passed, a copy will be made if it's
not in
CSR format.
y : Ignored
Not used, present here for API consistency by
convention.
sample_weight : array-like of shape (n_samples,),
default=None
The weights for each observation in X. If None, all
observations
are assigned equal weight.
.. versionadded:: 0.20
Returns
-------
self
Fitted estimator.
"""
random_state = check_random_state(self.random_state)
if self.precompute_distances != 'deprecated':
warnings.warn("'precompute_distances' was
deprecated in version "
"0.23 and will be removed in 0.25. It has no "
"effect",
FutureWarning)
if self.n_jobs != 'deprecated':
warnings.warn("'n_jobs' was deprecated in version
0.23 and will be"
" removed in 0.25.",
FutureWarning)
self._n_threads = self.n_jobs
else:
self._n_threads = None
self._n_threads = _openmp_effective_n_threads(self.
_n_threads)
n_init = self.n_init
if n_init <= 0:
raise ValueError("Invalid number of initializations."
" n_init=%d must be bigger than zero." %
n_init)
if self.max_iter <= 0:
raise ValueError(
'Number of iterations should be a positive number,'
' got %d instead' %
self.max_iter)
X = self._validate_data(X, accept_sparse='csr',
dtype=[np.float64, np.float32],
order='C', copy=self.copy_x,
accept_large_sparse=False)
# verify that the number of samples given is larger than k
if _num_samples(X) < self.n_clusters:
raise ValueError("n_samples=%d should be >=
n_clusters=%d" % (
_num_samples(X), self.n_clusters))
tol = _tolerance(X, self.tol)
# Validate init array
init = self.init
if hasattr(init, '__array__'):
init = check_array(init, dtype=X.dtype.type,
copy=True, order='C')
_validate_center_shape(X, self.n_clusters, init)
if n_init != 1:
warnings.warn('Explicit initial center position
passed: '
'performing only one init in k-means instead of
n_init=%d' %
n_init, RuntimeWarning, stacklevel=2)
n_init = 1 # subtract of mean of x for more accurate
distance computations
if not sp.issparse(X):
X_mean = X.mean(axis=0) # The copy was already
done above
X -= X_mean
if hasattr(init, '__array__'):
init -= X_mean
# precompute squared norms of data points
x_squared_norms = row_norms(X, squared=True)
best_labels, best_inertia, best_centers = None, None,
None
algorithm = self.algorithm
if algorithm == "elkan" and self.n_clusters == 1:
warnings.warn("algorithm='elkan' doesn't make sense
for a single "
"cluster. Using 'full' instead.",
RuntimeWarning)
algorithm = "full"
if algorithm == "auto":
algorithm = "full" if self.n_clusters == 1 else "elkan"
if algorithm == "full":
kmeans_single = _kmeans_single_lloyd
elif algorithm == "elkan":
kmeans_single = _kmeans_single_elkan
else:
raise ValueError(
"Algorithm must be 'auto', 'full' or 'elkan', got"
" {}".
format(str(algorithm))) # seeds for the initializations
of the kmeans runs.
seeds = random_state.randint(np.iinfo(np.int32).max,
size=n_init)
for seed in seeds:
# run a k-means once
labels, inertia, centers, n_iter_ = kmeans_single(X,
sample_weight, self.n_clusters, max_iter=self.max_iter,
init=init, verbose=self.verbose, tol=tol,
x_squared_norms=x_squared_norms,
random_state=seed,
n_threads=self._n_threads)
# determine if these results are the best so far
if best_inertia is None or inertia < best_inertia:
best_labels = labels.copy()
best_centers = centers.copy()
best_inertia = inertia
best_n_iter = n_iter_
if not sp.issparse(X):
if not self.copy_x:
X += X_mean
best_centers += X_mean
distinct_clusters = len(set(best_labels))
if distinct_clusters < self.n_clusters:
warnings.warn("Number of distinct clusters ({}) found
smaller than "
"n_clusters ({}). Possibly due to duplicate points "
"in X.".
format(distinct_clusters, self.n_clusters),
ConvergenceWarning, stacklevel=2)
self.cluster_centers_ = best_centers
self.labels_ = best_labels
self.inertia_ = best_inertia
self.n_iter_ = best_n_iter
return self
def fit_predict(self, X, y=None, sample_weight=None):
"""Compute cluster centers and predict cluster index for
each sample.
Convenience method; equivalent to calling fit(X)
followed by
predict(X).
Parameters
----------
X : {array-like, sparse matrix} of shape (n_samples,
n_features)
New data to transform.
y : Ignored
Not used, present here for API consistency by
convention.
sample_weight : array-like of shape (n_samples,),
default=None
The weights for each observation in X. If None, all
observations
are assigned equal weight.
Returns
-------
labels : ndarray of shape (n_samples,)
Index of the cluster each sample belongs to.
"""
return self.fit(X, sample_weight=sample_weight).labels_
def fit_transform(self, X, y=None, sample_weight=None):
"""Compute clustering and transform X to cluster-
distance space.
Equivalent to fit(X).transform(X), but more efficiently
implemented.
Parameters
----------
X : {array-like, sparse matrix} of shape (n_samples,
n_features)
New data to transform.
y : Ignored
Not used, present here for API consistency by
convention.
sample_weight : array-like of shape (n_samples,),
default=None
The weights for each observation in X. If None, all
observations
are assigned equal weight.
Returns
-------
X_new : array of shape (n_samples, n_clusters)
X transformed in the new space.
"""
# Currently, this just skips a copy of the data if it is not in
# np.array or CSR format already.
# XXX This skips _check_test_data, which may change
the dtype;
# we should refactor the input validation.
return self.fit(X, sample_weight=sample_weight).
_transform(X)
def transform(self, X):
"""Transform X to a cluster-distance space.
In the new space, each dimension is the distance to the
cluster
centers. Note that even if X is sparse, the array returned
by
`transform` will typically be dense.
Parameters
----------
X : {array-like, sparse matrix} of shape (n_samples,
n_features)
New data to transform.
Returns
-------
X_new : ndarray of shape (n_samples, n_clusters)
X transformed in the new space.
"""
check_is_fitted(self)
X = self._check_test_data(X)
return self._transform(X)
def _transform(self, X):
"""guts of transform method; no input validation"""
return euclidean_distances(X, self.cluster_centers_)
def predict(self, X, sample_weight=None):
"""Predict the closest cluster each sample in X belongs
to.
In the vector quantization literature, `cluster_centers_` is
called
the code book and each value returned by `predict` is
the index of
the closest code in the code book.
Parameters
----------
X : {array-like, sparse matrix} of shape (n_samples,
n_features)
New data to predict.
sample_weight : array-like of shape (n_samples,),
default=None
The weights for each observation in X. If None, all
observations
are assigned equal weight.
Returns
-------
labels : ndarray of shape (n_samples,)
Index of the cluster each sample belongs to.
"""
check_is_fitted(self)
X = self._check_test_data(X)
x_squared_norms = row_norms(X, squared=True)
return _labels_inertia(X, sample_weight,
x_squared_norms, self.cluster_centers_, self._n_threads)[0]
def score(self, X, y=None, sample_weight=None):
"""Opposite of the value of X on the K-means objective.
Parameters
----------
X : {array-like, sparse matrix} of shape (n_samples,
n_features)
New data.
y : Ignored
Not used, present here for API consistency by
convention.
sample_weight : array-like of shape (n_samples,),
default=None
The weights for each observation in X. If None, all
observations
are assigned equal weight.
Returns
-------
score : float
Opposite of the value of X on the K-means objective.
"""
check_is_fitted(self)
X = self._check_test_data(X)
x_squared_norms = row_norms(X, squared=True)
return -_labels_inertia(X, sample_weight,
x_squared_norms, self.cluster_centers_)[1]