hbase之python利用thrift操作hbase数据和shell操作

简介:

前沿:

        以前都是用mongodb的,但是量大了,mongodb显得不那么靠谱,改成hbase撑起一个量级。


HBase是Apache Hadoop的数据库,能够对大型数据提供随机、实时的读写访问。HBase的目标是存储并处理大型的数据。HBase是一个开源的,分布式的,多版本的,面向列的存储模型。它存储的是松散型数据。

HBase提供了丰富的访问接口。

HBase Shell
Java clietn API
Jython、Groovy DSL、Scala
REST
Thrift(Ruby、Python、Perl、C++…)
MapReduce
Hive/Pig


hbase(main):001:0> 

#创建表

hbase(main):002:0* create 'blog','info','content'

0 row(s) in 2.0290 seconds

#查看表

hbase(main):003:0> list

TABLE                                                                           

blog                                                                            

test_standalone                                                                 

2 row(s) in 0.0270 seconds

#增添数据

hbase(main):004:0> put 'blog','1','info:editor','liudehua'

0 row(s) in 0.1340 seconds


hbase(main):005:0> put 'blog','1','info:address','bj'

0 row(s) in 0.0070 seconds


hbase(main):006:0> put 'blog','1','content:header','this is header'

0 row(s) in 0.0070 seconds


hbase(main):007:0> 

hbase(main):008:0* 

hbase(main):009:0* get 'blog','1'

COLUMN                CELL                                                      

 content:header       timestamp=1407464302384, value=this is header             

 info:address         timestamp=1407464281942, value=bj                         

 info:editor          timestamp=1407464270098, value=liudehua                   

3 row(s) in 0.0360 seconds


hbase(main):010:0> get 'blog','1','info'

COLUMN                                                 CELL                                                                                                                                                         

 info:address                                          timestamp=1407464281942, value=bj                                                                                                                            

 info:editor                                           timestamp=1407464270098, value=liudehua                                                                                                                      

2 row(s) in 0.0120 seconds


#这里是可以按照条件查询的。

hbase(main):012:0* scan 'blog'

ROW                                                    COLUMN+CELL                                                                                                                                                  

 1                                                     column=content:header, timestamp=1407464302384, value=this is header                                                                                         

 1                                                     column=info:address, timestamp=1407464281942, value=bj                                                                                                       

 1                                                     column=info:editor, timestamp=1407464270098, value=liudehua                                                                                                  

1 row(s) in 0.0490 seconds


hbase(main):013:0> 

hbase(main):014:0* put 'blog','1','content:header','this is header2'

0 row(s) in 0.0080 seconds


hbase(main):015:0> 

hbase(main):016:0* 

hbase(main):017:0* put 'blog','1','content:header','this is header3'

0 row(s) in 0.0050 seconds


hbase(main):018:0> scan 'blog'

ROW                                                    COLUMN+CELL                                                                                                                                                  

 1                                                     column=content:header, timestamp=1407464457128, value=this is header3                                                                                        

 1                                                     column=info:address, timestamp=1407464281942, value=bj                                                                                                       

 1                                                     column=info:editor, timestamp=1407464270098, value=liudehua                                                                                                  

1 row(s) in 0.0180 seconds


hbase(main):020:0> get 'blog','1','content:header'

COLUMN                                                 CELL                                                                                                                                                         

 content:header                                        timestamp=1407464457128, value=this is header3                                                                                                               

1 row(s) in 0.0090 seconds


hbase(main):021:0> 

原文:http://rfyiamcool.blog.51cto.com/1030776/1537505


#可以看到历史版本记录

hbase(main):022:0* get 'blog','1',{COLUMN => 'content:header',VERSIONS => 2}

COLUMN                                                 CELL                                                                                                                                                         

 content:header                                        timestamp=1407464457128, value=this is header3                                                                                                               

 content:header                                        timestamp=1407464454648, value=this is header2                                                                                                               

2 row(s) in 0.0100 seconds

#可以看到历史版本记录

hbase(main):023:0> get 'blog','1',{COLUMN => 'content:header',VERSIONS => 3}

COLUMN                                                 CELL                                                                                                                                                         

 content:header                                        timestamp=1407464457128, value=this is header3                                                                                                               

 content:header                                        timestamp=1407464454648, value=this is header2                                                                                                               

 content:header                                        timestamp=1407464302384, value=this is header                                                                                                                

3 row(s) in 0.0490 seconds


hbase(main):024:0> 


base用java来操作是最方便,也效率最高的方式。但java并非轻量级,不方便在任何环境下调试。而且不同的开发人员熟悉的语言不一样,开发效率也不一样。hbase 通过thrift,还可以用python,ruby,cpp,perl等语言来操作。


thrift是facebook开发开源的类似google的protobuf的远程调用组件。但protobuf只有数据的序列化,且只支持二进制协议,没有远程调用部分。protobuf原生支持cpp,python,java,另外还有第三方实现的objectc,ruby等语言。而thrift是实现了序列化,传输,协议定义,远程调用等功能,跨语言能力更多。某些方面二者可以互相替代,但一些方面则各有适用范围。

原文:http://rfyiamcool.blog.51cto.com/1030776/1537505


thrift的安装及thrift python的相关模块 ~

1
2
3
4
5
6
7
http: / / www.apache.org / dist / / thrift / 0.9 . 1 / thrift - 0.9 . 1.tar .gz
tar zxvf thrift - 0.8 . 0.tar .gz
cd thrift - 0.8 . 0
. / configure  - with - cpp = no
make
sudo make install
sudo pip install thrift


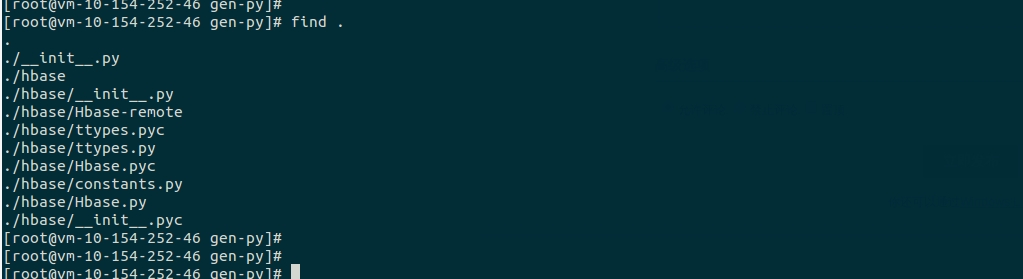
这里是可以生成python的thrift和hbase模块 ~

1
thrift  - gen py  / home / ubuntu / hbase - 0.98 . 1 / hbase - thrift / src / main / resources / org / apache / hadoop / hbase / thrift / Hbase.thrift


wKiom1PkaziSW8boAAFfmCFA2DA129.jpg


1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
from  thrift.transport  import  TSocket
 
from  thrift.protocol  import  TBinaryProtocol
 
from  hbase  import  Hbase
 
transport = TSocket.TSocket( 'localhost' , 9090 )
 
protocol = TBinaryProtocol.TBinaryProtocol(transport)
 
client = Hbase.Client(protocol)
 
transport. open ()
 
client.getTableNames()


原文:http://rfyiamcool.blog.51cto.com/1030776/1537505


hbase 0.98的版本 貌似没有thrift的相关组建,我这里的用的是0.94版本搞定的。  


 本文转自 rfyiamcool 51CTO博客,原文链接:http://blog.51cto.com/rfyiamcool/1537505,如需转载请自行联系原作者



相关文章
|
缓存 监控 Shell
如何使用 HBase Shell 进行数据的实时监控和备份?
526 5
|
Shell 分布式数据库 Hbase
如何使用 HBase Shell 进行数据的批量导入和导出?
1579 5
|
分布式计算 Hadoop Shell
Hadoop-35 HBase 集群配置和启动 3节点云服务器 集群效果测试 Shell测试
539 4
|
分布式计算 Hadoop Shell
Hadoop-36 HBase 3节点云服务器集群 HBase Shell 增删改查 全程多图详细 列族 row key value filter
427 3
|
Unix Shell Python
在Shell中转换Python正则表达式
结合以上提到的注意事项与差异点,就能在Shell环境中巧妙地转换并使用Python正则表达式了。务实和节省时间的做法是,将一些常见Python正则模式记在手边,随时查阅并对照POSIX标准进行调整。同时,借助在线正则表达式测试器和文档也能有效地提升在Shell环境中处理正则表达式的能力。
318 5
|
Shell 分布式数据库 Ruby
HBase常用shell操作(未完成)
HBase常用shell操作(未完成)
454 1
|
监控 网络协议 网络安全
SMTP操作使用详解并通过python进行smtp邮件发送示例
1073 3
|
安全 数据安全/隐私保护 Python
|
Serverless 语音技术 开发工具
函数计算操作报错合集之怎么何集成nls tts python sdk
在使用函数计算服务(如阿里云函数计算)时,用户可能会遇到多种错误场景。以下是一些常见的操作报错及其可能的原因和解决方法,包括但不限于:1. 函数部署失败、2. 函数执行超时、3. 资源不足错误、4. 权限与访问错误、5. 依赖问题、6. 网络配置错误、7. 触发器配置错误、8. 日志与监控问题。
445 2
|
API Python
Python高手修炼手册:精通文件系统操作,掌控I/O管理,提升编程效率
【7月更文挑战第30天】在 Python 编程中, 文件系统操作与 I/O 管理是连接程序与数据的关键。初学者常因路径错误和权限问题受挫, 而高手能自如管理文件。传统 `os` 和 `os.path` 模块易出错, `pathlib` 提供了更直观的对象导向 API。I/O 方面, 同步操作会阻塞程序, 异步 (如使用 `aiofiles`) 则能大幅提升并发能力。真正的高手不仅掌握 API, 更能预见性能瓶颈并优化代码, 实现高效与优雅。
367 1

推荐镜像

更多