NRTI/L3_AER_AI
This dataset provides near real-time high-resolution imagery of the UV Aerosol Index (UVAI), also called the Absorbing Aerosol Index (AAI).
The AAI is based on wavelength-dependent changes in Rayleigh scattering in the UV spectral range for a pair of wavelengths. The difference between observed and modelled reflectance results in the AAI. When the AAI is positive, it indicates the presence of UV-absorbing aerosols like dust and smoke. It is useful for tracking the evolution of episodic aerosol plumes from dust outbreaks, volcanic ash, and biomass burning.
The wavelengths used have very low ozone absorption, so unlike aerosol optical thickness measurements, AAI can be calculated in the presence of clouds. Daily global coverage is therefore possible.
For this L3 AER_AI product, the absorbing_aerosol_index is calculated with a pair of measurements at the 354 nm and 388 nm wavelengths.
该数据集提供了紫外线气溶胶指数 (UVAI) 的近实时高分辨率图像,也称为吸收气溶胶指数 (AAI)。
AAI 基于一对波长的 UV 光谱范围内瑞利散射的波长相关变化。观察到的和模拟的反射率之间的差异导致了 AAI。当 AAI 为正值时,表明存在吸收紫外线的气溶胶,如灰尘和烟雾。它可用于跟踪粉尘爆发、火山灰和生物质燃烧引起的偶发气溶胶羽流的演变。
所使用的波长对臭氧的吸收非常低,因此与气溶胶光学厚度测量不同,AAI 可以在有云的情况下计算。因此,每日全球报道是可能的。
对于此 L3 AER_AI 产品,吸收气溶胶指数是通过在 354 nm 和 388 nm 波长处进行的一对测量计算得出的。
NRTI L3 Product
To make our NRTI L3 products, we use harpconvert to grid the data.
Example harpconvert invocation for one tile:
harpconvert --format hdf5 --hdf5-compression 9
-a 'absorbing_aerosol_index_validity>50;derive(datetime_stop {time});
bin_spatial(2001, 50.000000, 0.01, 2001, -120.000000, 0.01);
keep(absorbing_aerosol_index,sensor_altitude,sensor_azimuth_angle,
     sensor_zenith_angle,solar_azimuth_angle,solar_zenith_angle)'
S5P_NRTI_L2__AER_AI_20181113T080042_20181113T080542_05618_01_010200_20181113T083707.nc
output.h5
Sentinel-5 Precursor
Sentinel-5 Precursor is a satellite launched on 13 October 2017 by the European Space Agency to monitor air pollution. The onboard sensor is frequently referred to as Tropomi (TROPOspheric Monitoring Instrument).
All of the S5P datasets, except CH4, have two versions: Near Real-Time (NRTI) and Offline (OFFL). CH4 is available as OFFL only. The NRTI assets cover a smaller area than the OFFL assets, but appear more quickly after acquisition. The OFFL assets contain data from a single orbit (which, due to half the earth being dark, contains data only for a single hemisphere).
Because of noise on the data, negative vertical column values are often observed in particular over clean regions or for low SO2 emissions. It is recommended not to filter these values except for outliers, i.e. for vertical columns lower than -0.001 mol/m^2.
The original Sentinel 5P Level 2 (L2) data is binned by time, not by latitude/longitude. To make it possible to ingest the data into Earth Engine, each Sentinel 5P L2 product is converted to L3, keeping a single grid per orbit (that is, no aggregation across products is performed).
Source products spanning the antimeridian are ingested as two Earth Engine assets, with suffixes _1 and _2.
The conversion to L3 is done by the harpconvert tool using the bin_spatial operation. The source data is filtered to remove pixels with QA values less than:
- 80% for AER_AI
- 75% for the tropospheric_NO2_column_number_density band of NO2
- 50% for all other datasets except for O3 and SO2
The O3_TCL product is ingested directly (without running harpconvert).
Dataset Availability
2018-07-10T11:17:44 - 2021-09-05T00:00:00
Dataset Provider
Collection Snippet
ee.ImageCollection("COPERNICUS/S5P/NRTI/L3_AER_AI")
Resolution
0.01 degrees
Bands Table
| Name | Description | Min* | Max* | Units |
| absorbing_aerosol_index | A measure of the prevalence of aerosols in the atmosphere, calculated by [this equation](https://earth.esa.int/web/sentinel/technical-guides/sentinel-5p/level-2/aerosol-index) using the 354/388 wavelength pair. | -25 | 39 | |
| sensor_altitude | Altitude of the satellite with respect to the geodetic sub-satellite point (WGS84). | 828543 | 856078 | m |
| sensor_azimuth_angle | Azimuth angle of the satellite at the ground pixel location (WGS84); angle measured East-of-North. | -180 | 180 | degrees |
| sensor_zenith_angle | Zenith angle of the satellite at the ground pixel location (WGS84); angle measured away from the vertical. | 0.09 | 67 | degrees |
| solar_azimuth_angle | Azimuth angle of the Sun at the ground pixel location (WGS84); angle measured East-of-North. | -180 | 180 | degrees |
| solar_zenith_angle | Zenith angle of the satellite at the ground pixel location (WGS84); angle measured away from the vertical. | 8 | 88 | degrees |
* = Values are estimated
影像属性:
| Name | Type | Description |
| ALGORITHM_VERSION | String | The algorithm version used in L2 processing. It's separate from the processor (framework) version, to accommodate different release schedules for different products. |
| BUILD_DATE | String | The date, expressed as milliseconds since 1 Jan 1970, when the software used to perform L2 processing was built. |
| HARP_VERSION | Int | The version of the HARP tool used to grid the L2 data into an L3 product. |
| INSTITUTION | String | The institution where data processing from L1 to L2 was performed. |
| L3_PROCESSING_TIME | Int | The date, expressed as milliseconds since 1 Jan 1970, when Google processed the L2 data into L3 using harpconvert. |
| LAT_MAX | Double | The maximum latitude of the asset (degrees). |
| LAT_MIN | Double | The minimum latitude of the asset (degrees). |
| LON_MAX | Double | The maximum longitude of the asset (degrees). |
| LON_MIN | Double | The minimum longitude of the asset (degrees). |
| ORBIT | Int | The orbit number of the satellite when the data was acquired. |
| PLATFORM | String | Name of the platform which acquired the data. |
| PROCESSING_STATUS | String | The processing status of the product on a global level, mainly based on the availability of auxiliary input data. Possible values are "Nominal" and "Degraded". |
| PROCESSOR_VERSION | String | The version of the software used for L2 processing, as a string of the form "major.minor.patch". |
| PRODUCT_ID | String | Id of the L2 product used to generate this asset. |
| PRODUCT_QUALITY | String | Indicator that specifies whether the product quality is degraded or not. Allowed values are "Degraded" and "Nominal". |
| SENSOR | String | Name of the sensor which acquired the data. |
| SPATIAL_RESOLUTION | String | Spatial resolution at nadir. For most products this is `3.5x7km2`, except for `L2__O3__PR`, which uses `28x21km2`, and `L2__CO____` and `L2__CH4___`, which both use `7x7km2`. This attribute originates from the CCI standard. |
| TIME_REFERENCE_DAYS_SINCE_1950 | Int | Days from 1 Jan 1950 to when the data was acquired. |
| TIME_REFERENCE_JULIAN_DAY | Double | The Julian day number when the data was acquired. |
| TRACKING_ID | String | UUID for the L2 product file. |
数据提供:
The use of Sentinel data is governed by the Copernicus Sentinel Data Terms and Conditions.
代码:
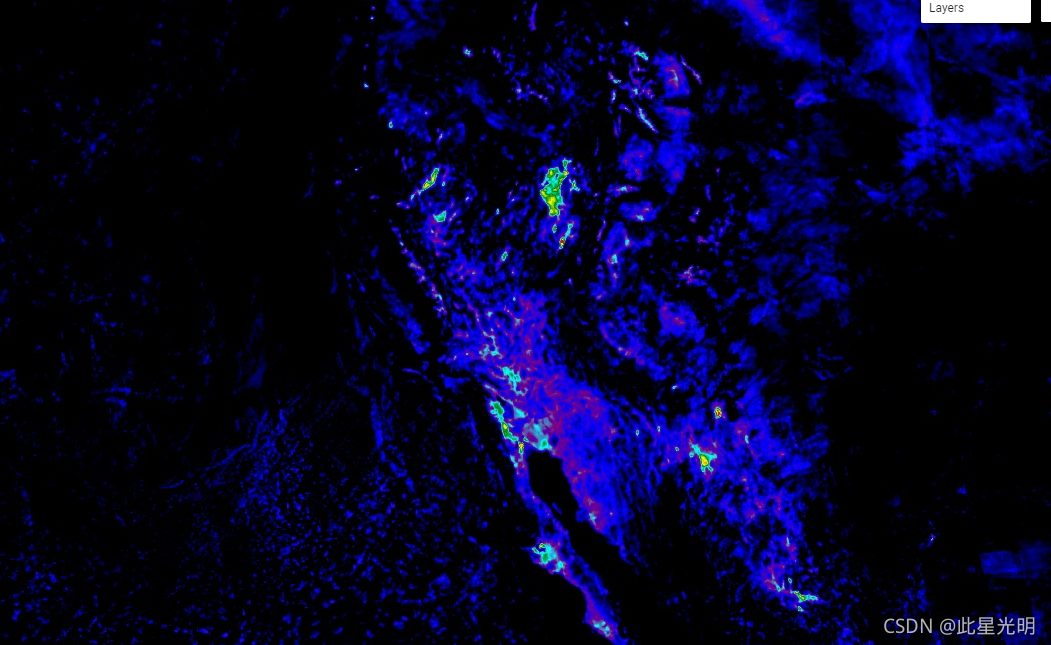
var collection = ee.ImageCollection('COPERNICUS/S5P/NRTI/L3_AER_AI')
  .select('absorbing_aerosol_index')
  .filterDate('2019-06-01', '2019-06-06');
var band_viz = {
  min: -1,
  max: 2.0,
  palette: ['black', 'blue', 'purple', 'cyan', 'green', 'yellow', 'red']
};
Map.addLayer(collection.mean(), band_viz, 'S5P Aerosol');
Map.setCenter(-118.82, 36.1, 5);