爬取拉勾网招聘信息,可以自定义搜索关键字。并把搜索结果保存在 excel 表格中
|
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
|
# -*- coding:utf-8 -*-
import
requests,json,xlwt
kd
=
'linux'
items
=
[]
def
get_content(pn):
#url和data通过F12查看Network->XHR->Headers->Request URL和Form Data
url
=
'https://www.lagou.com/jobs/positionAjax.json?needAddtionalResult=false'
data
=
{
'first'
:
'true'
,
'pn'
:pn,
'kd'
:kd}
#url发送一个post请求,把data数据发送过去
html
=
requests.post(url,data).text
#获取文本
html
=
json.loads(html)
#json格式字符串解码转换成python字典对象
#print html
for
i
in
range
(
14
):
#每页15项职位
item
=
[]
#下面参数通过F12查看Network->XHR->Preview->content->positionResult->result
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'positionName'
])
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'companyFullName'
])
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'salary'
])
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'city'
])
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'positionAdvantage'
])
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'companyLabelList'
])
item.append(html[
'content'
][
'positionResult'
][
'result'
][i][
'firstType'
])
items.append(item)
#print items
return
items
def
excel_write(items):
newTable
=
'test.xls'
wb
=
xlwt.Workbook(encoding
=
'utf-8'
)
#创建表格文件
ws
=
wb.add_sheet(
'test1'
)
#创建表
headData
=
[
'招聘职位'
,
'公司'
,
'薪资'
,
'地区'
,
'福利'
,
'提供条件'
,
'工作类型'
]
#定义表格首行信息
for
hd
in
range
(
0
,
7
):
ws.write(
0
,hd,headData[hd],xlwt.easyxf(
'font: bold on'
))
#0行 hd列
#写数据
index
=
1
#从第二行开始写
for
item
in
items:
for
i
in
range
(
0
,
7
):
print
item[i]
ws.write(index,i,item[i])
index
+
=
1
#print index
wb.save(newTable)
#保存数据
if
__name__
=
=
"__main__"
:
for
pn
in
range
(
1
,
5
):
#爬取1-5页职位
items
=
get_content(pn)
excel_write(items)
|
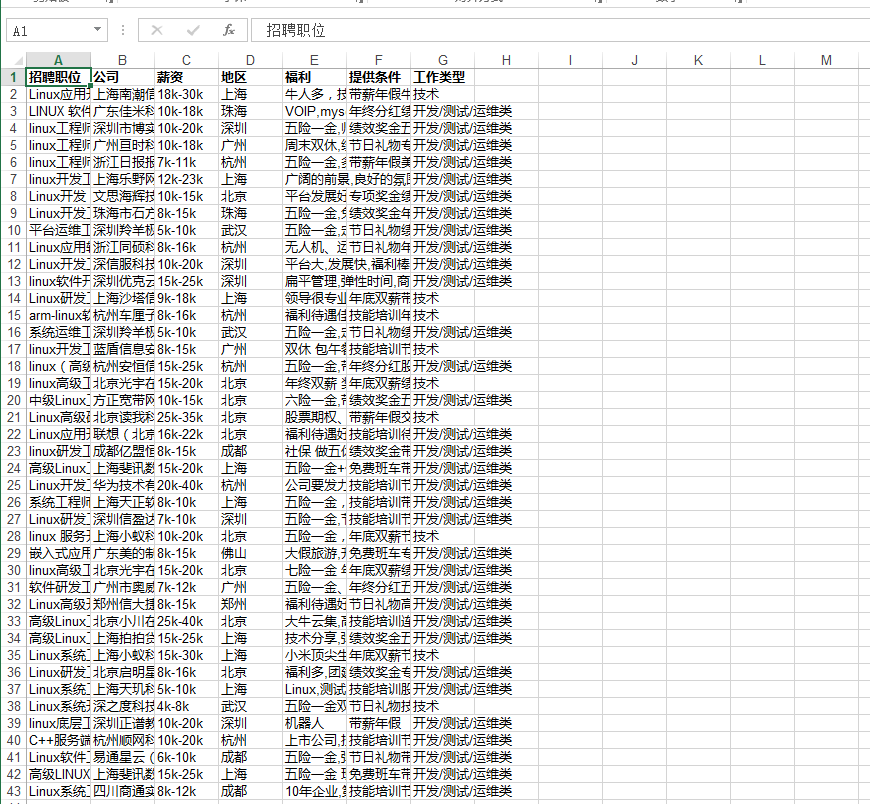
执行后,会在脚本同目录下生成一个 test.xls 表格,表格内容如下:
说明:需要安装三个模块
1、requests:请求页面
2、xlwt:写入表格(读取表格需要xlrd模块)
3、pyopenssl:不安装会报如下错误
C:\Python27\lib\requests\packages\urllib3\util\ssl_.py:335: SNIMissingWarning: An HTTPS request has been made, but the SNI (Subject Name Indication) extension to TLS is not available on this platform. This may cause the server to present an incorrect TLS certificate, which can cause validation failures. You can upgrade to a newer version of Python to solve this. For more information, see https://urllib3.readthedocs.io/en/latest/advanced-usage.html#ssl-warnings
SNIMissingWarning
C:\Python27\lib\requests\packages\urllib3\util\ssl_.py:133: InsecurePlatformWarning: A true SSLContext object is not available. This prevents urllib3 from configuring SSL appropriately and may cause certain SSL connections to fail. You can upgrade to a newer version of Python to solve this. For more information, see https://urllib3.readthedocs.io/en/latest/advanced-usage.html#ssl-warnings
InsecurePlatformWarning
本文转自M四月天 51CTO博客,原文链接:http://blog.51cto.com/msiyuetian/1930193,如需转载请自行联系原作者