Swipe for Chinese >>>
News Today
Qwen3-LiveTranslate-Flash: Real‑Time Multimodal Interpretation — See It, Hear It, Speak It

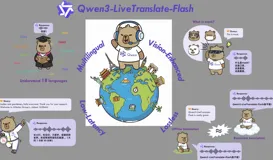
Qwen3-LiveTranslate-Flash delivers high‑precision, lightning‑fast and ultra‑reliable real‑time multilingual audio and video interpretation. With the extensive capabilities of Qwen3‑Omni and training on millions of hours of multimodal data, it enables both offline and live translation in 18 languages, making cross‑language communication seamless.
Key Features:
- Multilingual and Dialect Coverage: Supports major official languages including Chinese, English, French, German, Russian, Italian, Spanish, Portuguese, Japanese, Korean, Indonesian, Thai, Vietnamese, Arabic, Hindi, Greek, Turkish; as well as dialect and accent translation for Mandarin, Cantonese, Beijing, Wu, Sichuan, and Tianjin dialects.
- Vision‑Enhanced Comprehension: For the first time, Qwen3‑LiveTranslate‑Flash incorporates visual context augmentation, enabling it to not only understand what it hears but also understand what it sees. By detecting and interpreting lip movements, gestures, on‑screen text, and real‑world entities, the system robustly handles noisy audio environments and resolves ambiguities in terms with multiple meanings.
- 3s Latency: A lightweight mixture‑of‑experts architecture, coupled with dynamic sampling, enables simultaneous interpretation with latency as low as three seconds.
- Lossless Interpretation: Utilizes semantic unit prediction to mitigate cross‑lingual reordering challenges in translation, achieving real‑time translation quality that is close to offline translation.
- Natural Voice Quality: With training on massive speech datasets, the model delivers lifelike voices whose tone and expressiveness naturally follow the meaning of the source speech.
 Performance
Qwen3‑LiveTranslate‑Flash achieves significantly higher accuracy than strong large-scale models, including Gemini‑2.5‑Flash, GPT‑4o‑Audio‑Preview, and Voxtral Small‑24B, on public benchmarks for Chinese, English and multilingual speech translation.

Qwen3‑LiveTranslate‑Flash consistently delivers leading translation performance across different domains and under challenging acoustic conditions.

Semantic unit prediction technology alleviates cross-lingual reordering issues, enabling real-time simultaneous interpretation to significantly reduce latency while maintaining over 94% of the accuracy achieved by non-real-time translation.
Visual enhancement technology further improves Qwen3-LiveTranslate-Flash’s translation precision in challenging scenarios such as noisy audio, ambiguous word meanings, and proper noun translation. In real-time settings, visual information compensates for missing speech context, making its advantages even more pronounced.

 Examples
1  Speech‑to‑Speech Simultaneous Translation
Local API Test: real‑time interpretation | English → Chinese
2  Vision‑Enhanced Speech Translation
Homophones / Ambiguous Terms | English → Chinese
 What's Next
Qwen will keep advancing the accuracy, naturalness, and emotional fidelity of our speech translation; extend coverage to more languages; and reinforce its robustness across varied and challenging acoustic environments. The goal is to bridge linguistic divides, enabling conversations to flow as smoothly and naturally as if speaking face to face.
/ END /
来源 | Alibaba Cloud Internationa公众号