文档 https://maartengr.github.io/BERTopic/algorithm/algorithm.html 提供了基本流程。
Document embeddings
克服了bag-of-words "disregard semantic relationships among words"的缺点
from sentence_transformers import SentenceTransformer
embedding_model = SentenceTransformer("DMetaSoul/Dmeta-embedding")
# 计算嵌入比较慢,可以pre-calculate
embeddings = embedding_model.encode(docs, show_progress_bar=True)
Document clustering
使用umap降维,使用hdbscan聚类
使用hdbscan的原因是"a cluster will not always lie within a sphere around a cluster centroid"
from umap import UMAP
from hdbscan import HDBSCAN

umap_model = UMAP(n_neighbors=15, n_components=5, min_dist=0.0, metric='cosine', random_state=42)
hdbscan_model = HDBSCAN(min_cluster_size=15, metric='euclidean', cluster_selection_method='eom', prediction_data=True)
参数n_neighbors和min_cluster_size相当于调整一个cluster的大小,n_components相当于输出的维度
Topic Representation
这部分是核心,分为vectorize、c-TF-IDF和fine-tune三部分
对于中文,需要分词
from sklearn.feature_extraction.text import CountVectorizer
import jieba

def tokenize_zh(text):
    words = jieba.lcut(text)
    return words

# by increasing the n-gram range we will consider topic representations that are made up of one or two words.
vectorizer = CountVectorizer(tokenizer=tokenize_zh, ngram_range=(1, 3))
The classic TF-IDF procedure combines two statistics, term frequency, and inverse document frequency. We generalize this procedure to clusters of documents. First, we treat all documents in a cluster as a single document by simply concatenating the documents. Then, TF-IDF is adjusted to account for this representation by translating documents to clusters.
from bertopic.vectorizers import ClassTfidfTransformer

ctfidf_model = ClassTfidfTransformer()
from bertopic.representation import KeyBERTInspired

# Create your representation model
# KeyBERTInspired可以减少stop words
representation_model = KeyBERTInspired()
然后把模型组装起来,训练模型
topic_model = BERTopic(
  embedding_model=embedding_model,          # Step 1 - Extract embeddings
  umap_model=umap_model,                    # Step 2 - Reduce dimensionality
  hdbscan_model=hdbscan_model,              # Step 3 - Cluster reduced embeddings
  vectorizer_model=vectorizer_model,        # Step 4 - Tokenize topics
  ctfidf_model=ctfidf_model,                # Step 5 - Extract topic words
  representation_model=representation_model, # Step 6 - (Optional) Fine-tune topic represenations
  verbose=True
)

topics, probs = topic_model.fit_transform(docs,
  embeddings # pre-calculate
)
看看生成了哪些主题
topic_model.get_topic_info()

topic_model.get_topic(0)
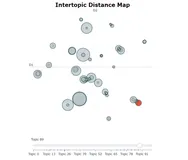
最后可视化一下吧
topic_model.visualize_topics()

topic_model.visualize_heatmap()
还可以保存和加载模型
topic_model.save("path/to/my/model_dir", serialization="safetensors", save_ctfidf=True, save_embedding_model=embedding_model)

loaded_model = BERTopic.load("path/to/my/model_dir")