0. 引言
elasticsearch官方的java客户端有tranport client,rest high level client,但进行索引的增删改查的操作不够简便。因此我们引入spring data elasticsearch来实现索引的CRUD
1. 版本对应关系
在引入spring data之前要先了解版本之间的对应关系,这个我们可以在spring data 官方文档中查询到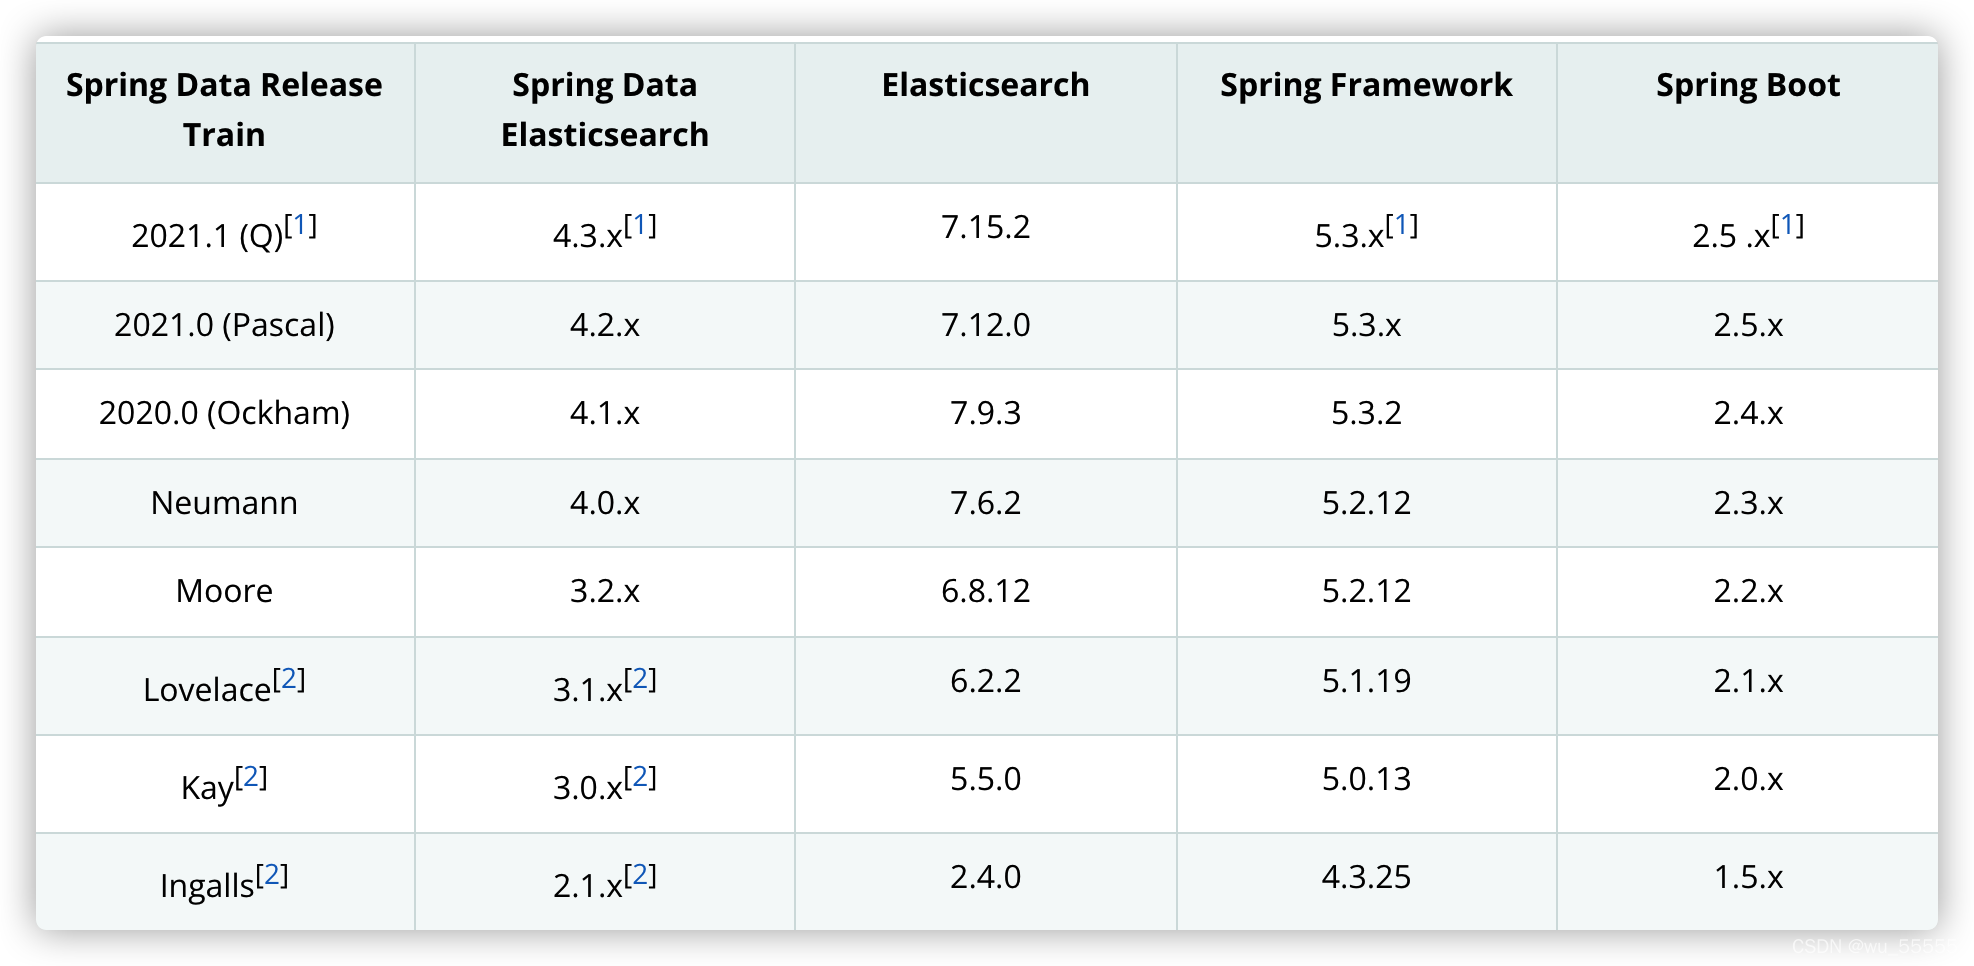
这里我的es用的7.14.0版本,所以需要引入spring data elasticsearch4.3.x版本的依赖
<dependency>
            <groupId>org.springframework.data</groupId>
            <artifactId>spring-data-elasticsearch</artifactId>
            <version>4.3.0</version>
</dependency>
需要注意的是,springboot也整合了spring data
<dependency>
           <groupId>org.springframework.boot</groupId>
           <artifactId>spring-boot-starter-data-elasticsearch</artifactId>
</dependency>
2. 实现CRUD
1、连接客户端配置,两种方式
(1)配置文件
spring:
  elasticsearch:
    rest:
      uris: http://localhost:9200 # 多个地址用逗号隔开
      username: elastic # es开启了security的需要添加用户名和账户
      password: elastic # es开启了security的需要添加用户名和账户
(2)配置类,官方推荐的方式
import org.springframework.beans.factory.annotation.Autowired;@Configuration
static class Config {

    @Bean
    RestHighLevelClient client() {
        HttpHeaders headers = new HttpHeaders();
        headers.setBasicAuth("elastic","elastic");

        ClientConfiguration clientConfiguration = ClientConfiguration.builder()
            .connectedTo("localhost:9200")
            .withDefaultHeaders(headers)
            .build();

        return RestClients.create(clientConfiguration).rest();
    }
}
2、创建实体类
/**
 * @author whx
 * @date 2022/1/6
 */
@Data
@Document(indexName = "user")
@Setting(
    replicas = 0
)
@NoArgsConstructor
public class UserES implements Serializable {
    private static final long serialVersionUID = 1L;
    /**
     * 用户ID
     */
    @Id
    private Long id;
    /**
     * 用户编码
     */
    @Field(type=FieldType.Keyword)
    private String code;
    /**
     * 用户平台
     */
    @Field(type=FieldType.Long)
    private Long userType;
    /**
     * 账号
     */
    @Field(type=FieldType.Text)
    private String account;
    /**
     * 昵称
     */
    @Field(type=FieldType.Text)
    private String name;
    /**
     * 真名
     */
    @Field(type=FieldType.Text)
    private String realName;
    /**
     * 邮箱
     */
    @Field(type=FieldType.Text)
    private String email;
    /**
     * 手机
     */
    @Field(type=FieldType.Keyword)
    private String phone;
    /**
     * 生日
     */
    @Field(type=FieldType.Date)
    private Date birthday;
    /**
     * 性别
     */
    @Field(type=FieldType.Integer)
    private Integer sex;
    /**
     * 角色ID
     */
    @Field(type=FieldType.Long)
    private List<Long> roleIds;
    /**
     * 所在直系部门ID
     */
    @Field(type=FieldType.Keyword)
    private List<String> deptIds;
    /**
     * 岗位ID
     */
    @Field(type=FieldType.Long)
    private List<Long> postIds;
    /**
     * 所有父级部门ID
     */
    @Field(type=FieldType.Long)
    private List<String> parentDeptIds;
    /**
     * 平台类型(微信用户专用)
     */
    @Field(type = FieldType.Keyword)
    private String clientId;
    /**
     * 第三方平台Id(微信用户专用)
     */
    @Field(type= FieldType.Keyword)
    private String thirdPlatformUserId;
    /**
     * PC绑定用户ID
     */
    @Field(type=FieldType.Long)
    private String tenantUserId;
    /**
     * 用户来源:0 pc 1 wx
     */
    @Field(type=FieldType.Integer)
    private Integer userSource;
    /**
     * 租户
     */
    @Field(type=FieldType.Keyword)
    private String tenantId;
    /**
     * 创建人
     */
    @Field(type=FieldType.Long)
    private Long createUser;
    /**
     * 创建部门
     */
    @Field(type=FieldType.Keyword)
    private String createDept;
    /**
     * 创建时间
     */
    @Field(type=FieldType.Date)
    private Date createTime;

}
因为我这里还需要将mysql数据同步到es中,所以还需要在UserES类中创建转换方法。这里的实体类转换大家可根据具体自己的需求来书写,以下仅供参考
    public static UserES build(User user){
        UserES userES = Objects.requireNonNull(BeanUtil.copy(user, UserES.class));
        userES.userSource = 0;
        if(!StringUtils.isEmpty(user.getRoleId())){
            userES.roleIds = java.util.Arrays.stream(user.getRoleId().split(",")).map(Long::parseLong).collect(Collectors.toList());
        }
        if(!StringUtils.isEmpty(user.getPostId())){
            userES.postIds = java.util.Arrays.stream(user.getPostId().split(",")).map(Long::parseLong).collect(Collectors.toList());
        }
        if(!StringUtils.isEmpty(user.getDeptId())){
            userES.deptIds = java.util.Arrays.stream(user.getDeptId().split(",")).collect(Collectors.toList());
        }
        return userES;
    }

    public static UserES build(UserWxmini user){
        UserES userES = Objects.requireNonNull(BeanUtil.copy(user, UserES.class));
        userES.userSource = 1;
        userES.name = user.getNickName();
        return userES;
    }

    public static List<UserES> buildList(List<User> list){
        return list.stream().map(UserES::build).collect(Collectors.toList());
    }

    public static List<UserES> buildUserWxList(List<UserWxmini> list){
        return list.stream().map(UserES::build).collect(Collectors.toList());
    }
3、创建repository接口,可以看到只需要继承ElasticsearchCrudRepository接口即可
/**
 * 用户ES客户端
 * @author whx
 * @date 2022/1/6
 */
public interface UserRepositoryElastic extends ElasticsearchCrudRepository<UserES,Long> {

}
4、ElasticsearchCrudRepository接口已经自带了常用的CRUD方法,我们可以直接拿来用
在serviceImpl类中引入UserRepositoryElastic
5、ElasticsearchCrudRepository接口常用的CRUD方法
deleteById(id);
findById(id);
findAll();
findAllById(ids);
save(new UserES());
existsById(id);
count();
3. 如何自定义方法
3.1 通过spring data自带的语法来自动生成衍生方法
如:根据名称来查询
public interface UserRepositoryElastic extends ElasticsearchCrudRepository<UserES,Long> {

    Page<UserES> findByName(String name,Pageable page);
}
支持的语法有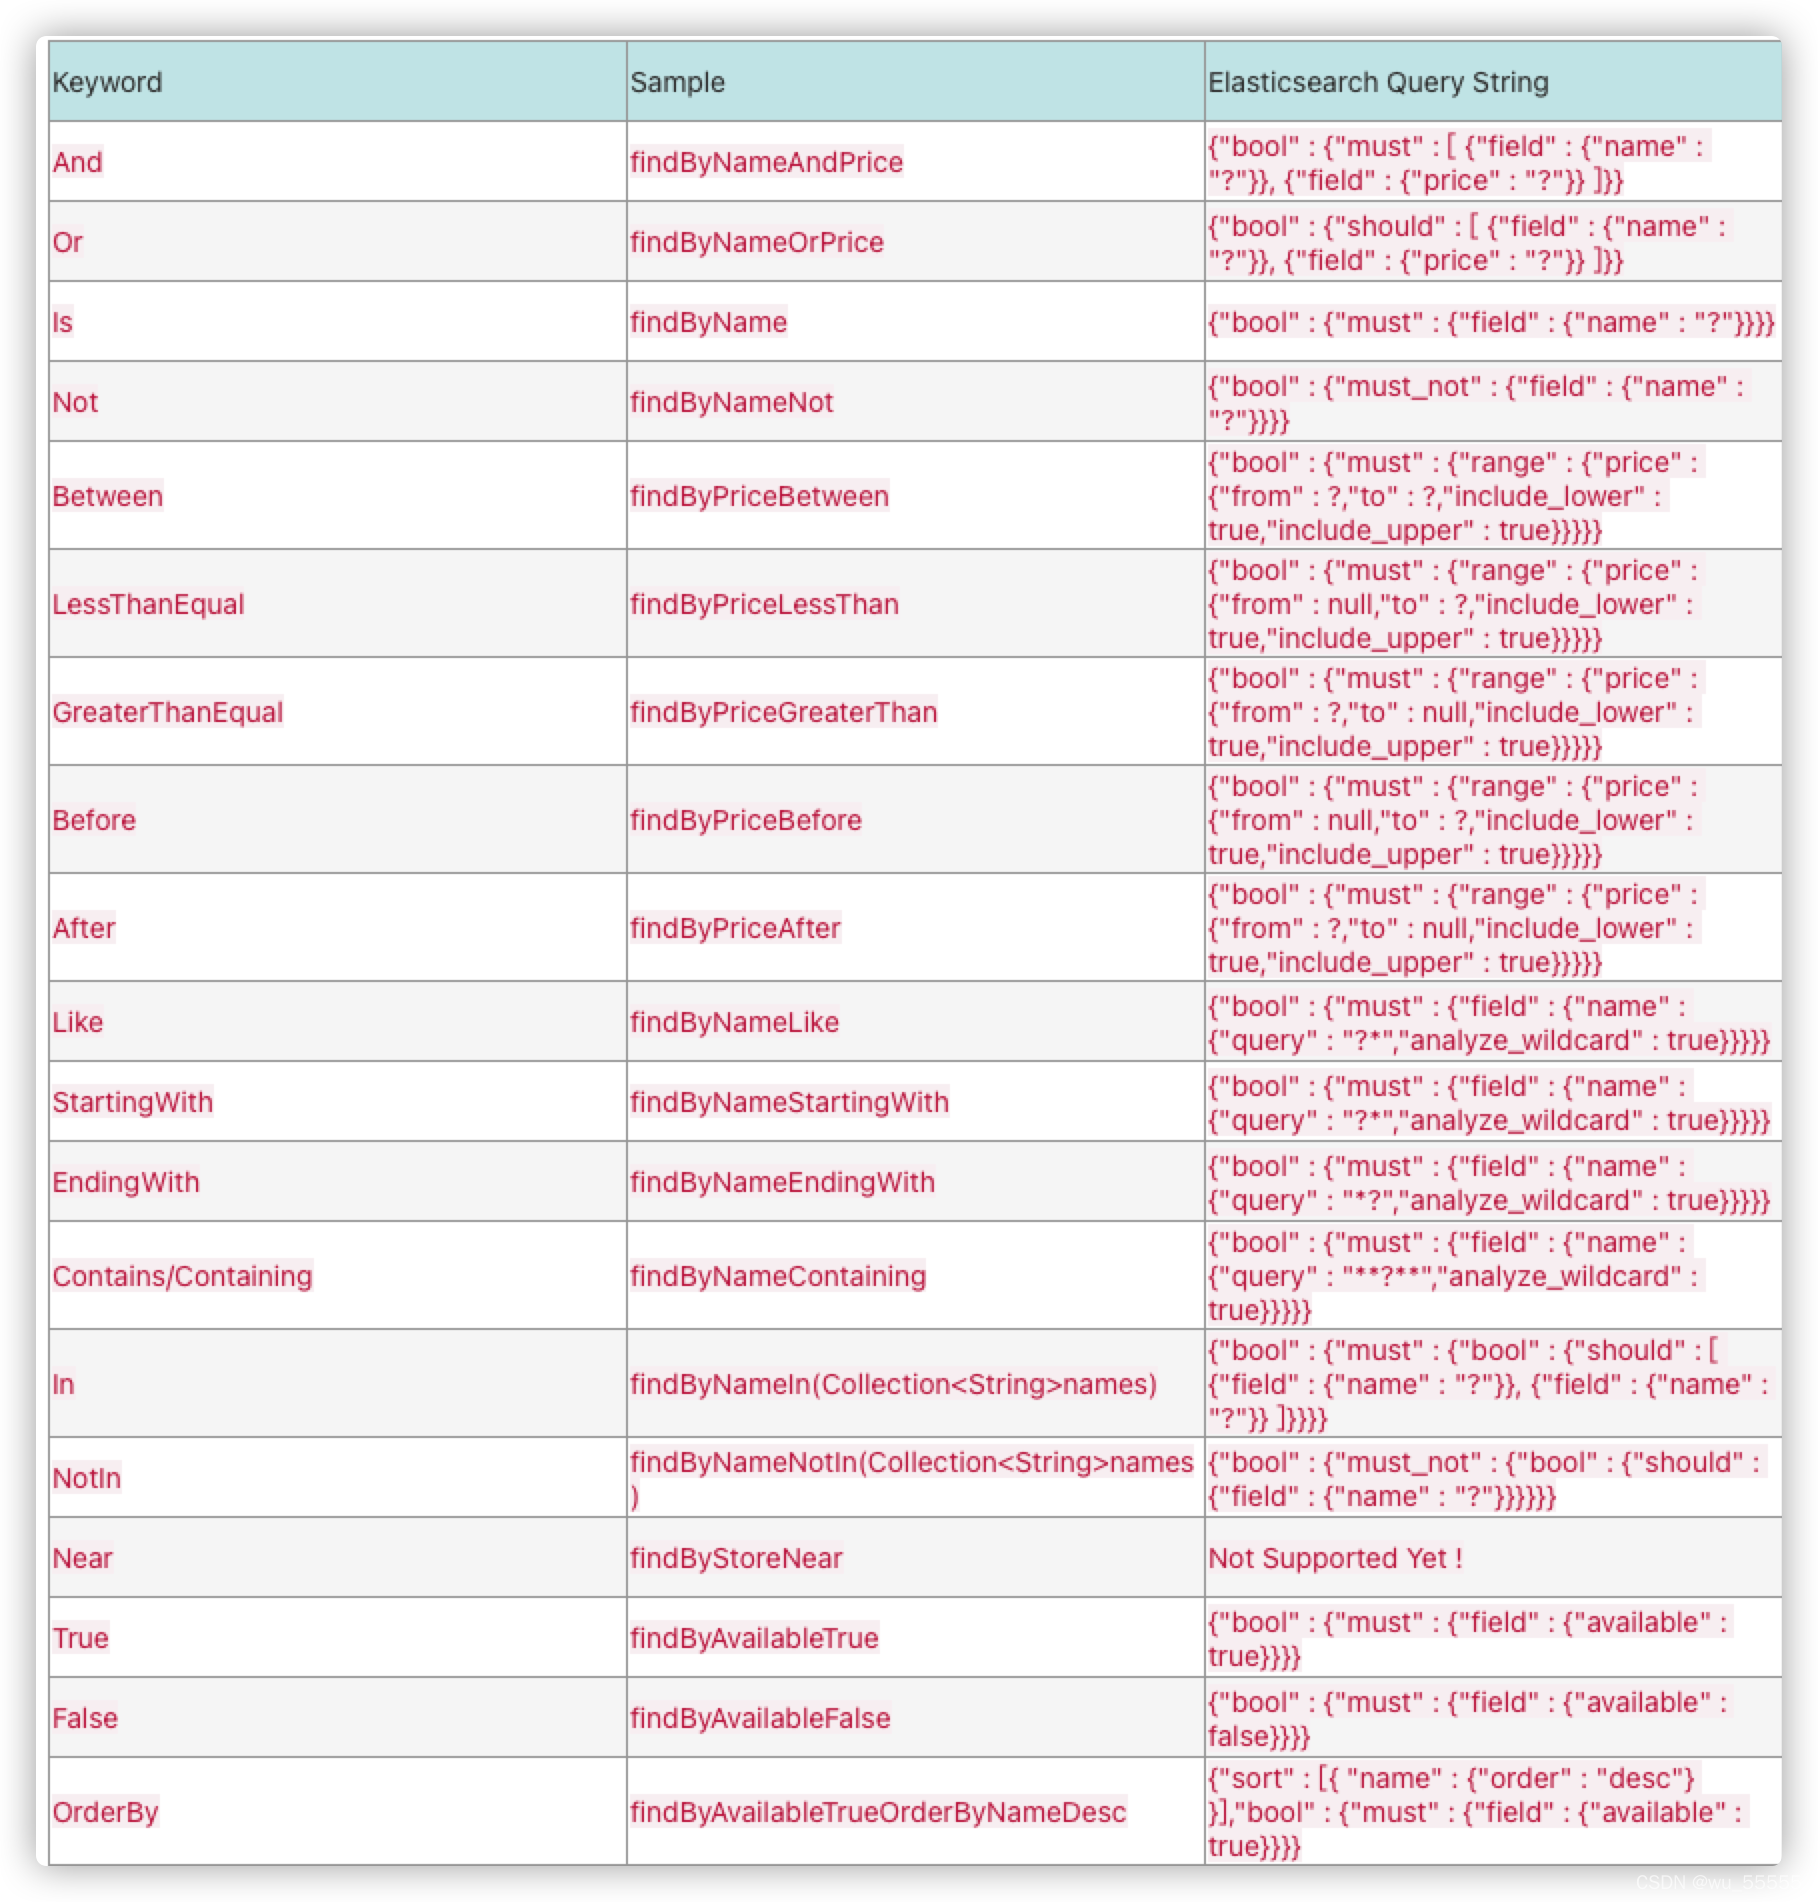
3.2 通过@Query自定义查询
query中的就是查询的DSL语句,?0表示第一个参数
@Query("{"bool" : {"must" : {"field" : {"name" : "?0"}}}}")
Page<EsProduct> findByName(String name,Pageable pageable);
3.3 聚合与其他操作
spring data elasticsearch本身也集合了TransportClient和HighLevelRestClient。所以对于复杂的聚合查询和其他操作时,仍然可以使用原生的client来实现
示例,通过HighLevelRestClient来实现聚合
@Autowired
 private ElasticsearchTemplate elasticsearchTemplate;

 //聚合
    public Map<String, Integer> polymerizationQuery() {
        String aggName = "popularBrand";
        NativeSearchQueryBuilder queryBuilder = new NativeSearchQueryBuilder();
        //聚合
        queryBuilder.addAggregation(AggregationBuilders.terms("popularBrand").field("brand"));
        //查询并返回带聚合结果
        AggregatedPage<Item> result = elasticsearchTemplate.queryForPage(queryBuilder.build(), Item.class);
        //解析聚合
        Aggregations aggregations = result.getAggregations();
        //获取指定名称的聚合
        StringTerms terms = aggregations.get(aggName);
        //获取桶
        List<StringTerms.Bucket> buckets = terms.getBuckets();
        //遍历打印
        Map<String, Integer> map = new HashMap<>();
        for (StringTerms.Bucket bucket : buckets) {
            map.put(bucket.getKeyAsString(), (int) bucket.getDocCount());
            System.out.println("key = " + bucket.getKeyAsString());
            System.out.println("DocCount = " + bucket.getDocCount());
        }
        return map;
}更多操作可以查看ES官方文档
针对复杂的操作更多的还是需要自己去实操才能熟练,如果有复杂DSL语句如果在java中是实现的问题,也可以留言告诉我,一起探讨。
4 mysql数据到es中
4.1 mysql全量同步至es中
全量同步应该只需要调用一次,后续的更新通过增量同步来实现
@Service
@AllArgsConstructor
public class UserServiceImpl extends BaseServiceImpl<UserMapper, User> implements IUserService {
    private final UserRepositoryElastic userRepositoryElastic;

    @Override
    @TenantIgnore
    public R transferFromMysqlToEs(){
        // 查询所有用户数据 (这里是直接调用的mybatis-plus框架自带的selectList方法)
        List<User> users = baseMapper.selectList(Wrappers.lambdaQuery());
        // 将所有用户数据同步到es中
        userRepositoryElastic.saveAll(UserES.buildList(users));
        return R.success("操作成功");
    }
}
4.2 mysql增量同步到es中
使用spring data elasticsearch的增量同步,就是通过在原有的操作代码中插入针对es的操作,比如新增修改用户信息时,同步修改es中的数据
public R<Boolean> submit(User user){
        boolean res = this.saveOrUpdate(user);
        if(res){
            userRepositoryElastic.save(UserES.build(user));
        }
        return R.data(res);
}
删除时同步删除es中的数据
public R remove(List<Long> ids){
        baseMapper.deleteBatchIds(ids);
        ids.forEach(userRepositoryElastic::deleteById);
        return R.success("删除成功");
}
4.3 优缺点
优点:通过spring data elasticsearch来同步数据,因为是基于代码实现,所以可以实现比较复杂的转换逻辑,无需部署第三方插件。
缺点:代码入侵性强,如果需要同步的业务数据种类较多,那么就需要大量修改源码,工作量大。且会增加原始方法的耗时。
5. mysql同步到ES的其他同步方案
5.1 通过canal实现mysql同步到ES
安装:通过canal实现mysql同步到ES
优点:基于bin log来实现,保障性能,无代码入侵。且可以通过自定义代码来实现数据转换。
缺点:需要安装和维护canal。有一致性要求的数据,需要做好canal集群的高可用。未开启binlog之前的历史数据无法实现全量同步,这一点可以通过logstash来补足
5.2 通过logstash-input-jdbc实现mysql同步到ES
安装:通过logstash-input-jdbc实现mysql同步到ES
优点:ELK体系下logstash的来实现,如果本身在使用ELK则无较大的部署成本,支持全量增量同步,无需开启bin log
缺点:需要安装和维护logstash,性能不如canal
5.3 推荐方案
使用logstash-input-jdbc来实现全量同步,canal来实现增量同步。
如果想用canal来实现全量+增量同步,那么可以将未开启binlog之前的数据重新导出再导入一遍,以此生成binlog,从而实现全量同