XuanTie C908 is the latest RISC-V processor of the XuanTie series launched by T-Head Semiconductor. It has adopted the RV64GCB[V] instruction and is compatible with RVA22 profile. XuanTie C908 utilizes a high-efficiency,dual-issued, and 9-stage in-order pipeline. It is equipped with an AI acceleration engine. It is designed to mainly suit for applications such as Intelligent Interaction, AR/VR.
Specifications and features
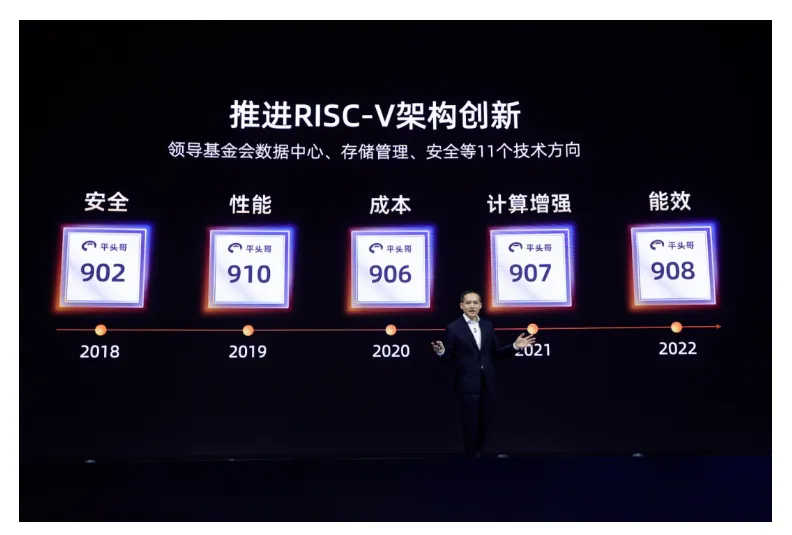
In 2019, T-Head Semiconductor released XuanTie C910, a high-performance multi-issue out-of-order processor. Later XuanTie C906, a low-cost single-issue in-order processor, had followed for launch. The newest XuanTie C908 is a high-efficiency processor targeted at the mid-end market segments for the growing market of image and video processing applications. Its performance and cost are between those of C910 and C906, filling the gap in the product line of XuanTie series processors
XuanTie C908 supports three privileged modes: Machine, Supervisor, and User. Among them, the User mode supports both RV64GCB[V] and RV32GCB[V] instruction sets. Softwares can switch among the modes during runtime through UXL. XuanTie C908 supports the RV32 COMPAT mode for the first time in the industry to meet the requirements in applications, e.g. IP Camera. Furthermore, it has been merged into the Linux mainline in version 5.19[1]. The RV32 COMPAT mode not only provides higher code density but also allows users to port 32-bit applications to XuanTie C908 in a faster manner.
XuanTie C908 supports the following features: RISC-V Bitmanip 1.0 instruction extension including the carry-less multiplication (zbc), optional supports RISC-V Vector 1.0 instruction set extension, BF16 operations, IEEE-754 compatible half-precision, and other floating-point operations. In addition, XuanTie C908 supports the RISC-V CMO Base extension and Svinval extension. It adopts the Sv39/Sv48 virtual address system and holds up Svnapot and Svpbmt. All these features make it possible for XuanTie C908 to be one of the first RISC-V processors for the upcoming RVA22 profile. XuanTie C908 also inherits XuanTie extensions, including Instruction, Memory Attributes Extension (XMAE).
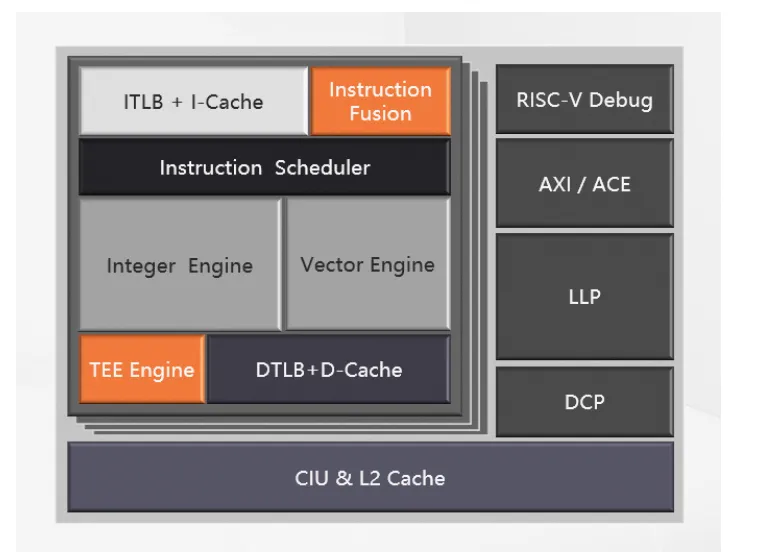
As illustrated in the above graph, XuanTie C908 uses a two-level cache system to support hardware cache coherency and optional ECC. In this multi-cluster architecture, each cluster can contain 1 to 4 cores.The bus interface supports AXI4/ACE protocol with two optional interfaces: a Device Coherence Port (DCP) and a Low Latency Port (LLP). DCP maintains data coherency with external I/O masters, while LLP accesse peripherals. In terms of peripherals, XuanTie C908 provides the enhanced physical memory protection (ePMP) unit that allows a maximum of 64 regions. C908 also backs up for RISC-V Debug and Platform-Level Interrupt Controller (PLIC), with which can be configured up to 1023 interrupt sources.
Microarchitecture and metrics
XuanTie C908 contains a 9-stage dual-issue in-order pipeline. It delivers industry-leading performance in control flow, computing, and frequency through architecture and micro-architecture innovations.
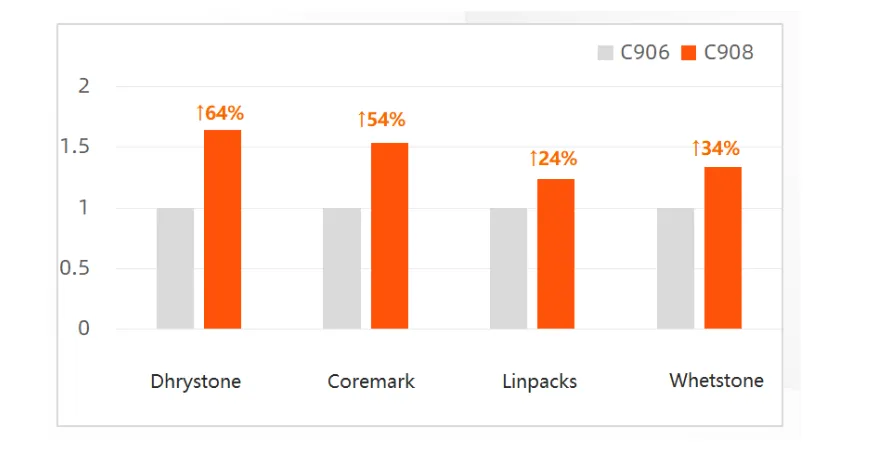 XuanTie C908 is the pillar for branch prediction technologies, including state-of-the-art Branch History Table, Branch Target Buffer, and Return Address Stack. It utilizes Instruction Fusion technology, which can fuse various types of instructions into a single instruction for execution. In addition, XuanTie C908 provides a brand-new data prefetching algorithm, further improving the memory access performance in complex application scenarios.
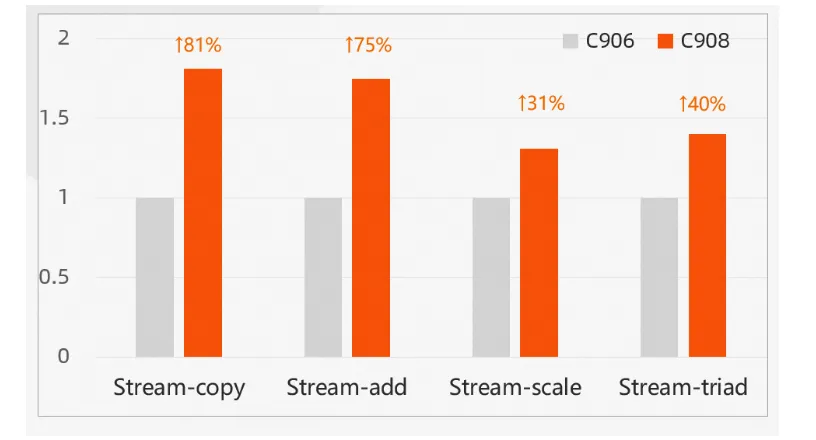 To further benefit from the efficient pipeline design, XuanTie C908 can run at a frequency of up to 2 GHz, and the dynamic power consumption can be 52.8 mW/GHz per core under TSMC's 12nm process. Under the same frequency and process constraints, the energy efficiency ratio of XuanTie C908 in typical scenarios can be improved by more than 20% compared with that of XuanTie C906.
AI-oriented software and hardware acceleration technology
XuanTie C908 includes an optional Vector Processing Unit (VPU), which is compatible with the RISC-V Vector Extension 1.0 specification. This feature supports various vector floating-point and integer data formats. The computing power of key operations, such as multiply-accumulate, are enhanced in different application scenarios. For typical AI application scenarios, XuanTie C908 supplies the vector dot product instruction extension and intruduces the INT4 data type. This helps to improve the peak computing power, while reducing the memory requirement. XuanTie C908 has outperformed C906 in the MLPerf tiny V0.7 inference performance test. The performance of C908 is up to more than 3.5 times that of C906.
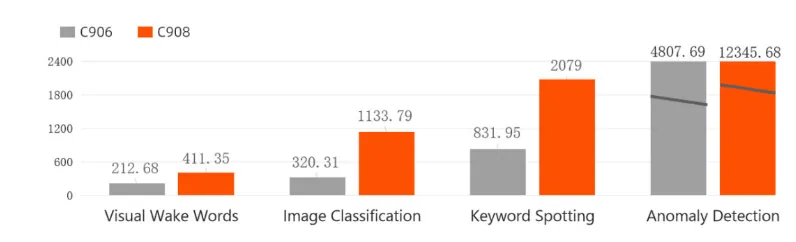
XuanTie C908 adopts co-design methodology to accelerate deep learning inference applications for both hardware and software. With the neural network inference deployment tool, i.e.HHB, and a high-performance heterogeneous computing library,i.e. SHL, XuanTie C908 is empowered and optimized with reference implementations of compilation and assembly.
Conclusion
XuanTie C908 has achieved technological breakthroughs for higher performance in RISC-V. XuanTie C908 supports a multi-core and multi-cluster architecture, adopts a high-efficiency 9-stage dual-issue in-order pipeline, and utilizes innovative instruction fusion technology to further improve efficiency. Its energy efficiency ratio has reached the industry's advanced level. Compatible with the latest RISC-V Vector 1.0 specification, XuanTie C908 introduces the INT4 data type and vector dot product instruction extension and provides a comprehensively optimized algorithm library, which helps drastically improve AI computing performance.
[1]: https://www.phoronix.com/news/Linux-5.19-RISC-V